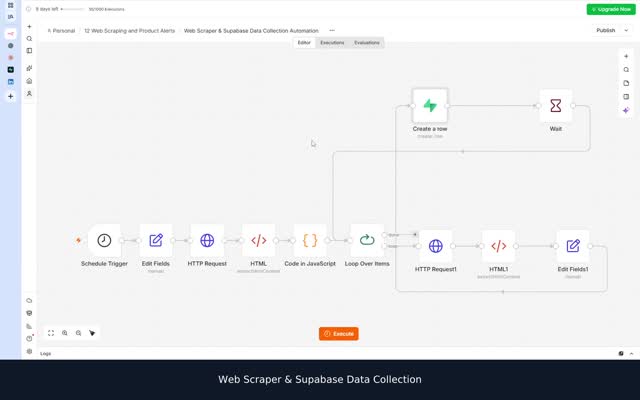
Product information on web pages needs to be processed before it can support a retrieval-based assistant.
DATA & INTEGRATIONS / PROJECT 17
Product Scraper & RAG Pipeline
Collect product page content and prepare it for retrieval using embeddings and a Supabase vector store.
Portfolio implementation · Demo available
01 / PROJECT OVERVIEW
Prepare product information for AI retrieval.
Collect product page content and prepare it for retrieval using embeddings and a Supabase vector store.
Collect product page content and prepare it for retrieval using embeddings and a Supabase vector store.
Product content is processed into chunks and embeddings for storage in the Supabase vector store.
Who it’s for
Businesses preparing a product knowledge base for retrieval-based AI assistants. This demo covers data ingestion and indexing.
02 / HOW IT WORKS
From input to outcome.
A simplified walkthrough of the workflow’s main stages.
- 01Collect product page links
- 02Fetch and extract product information
- 03Load and split the content into chunks
- 04Create embeddings and store vectors in Supabase
03 / FEATURES & TOOLS
What’s inside.
- Collect product page links
- Fetch and extract product information
- Load and split the content into chunks
- Create embeddings and store vectors in Supabase
Technologies used
Adapt this demo to your business
We’ll configure your tools, data and approval rules, then test the workflow with your process before launch.
04 / PROJECT DEMO
See the workflow in action.
KEEP EXPLORING